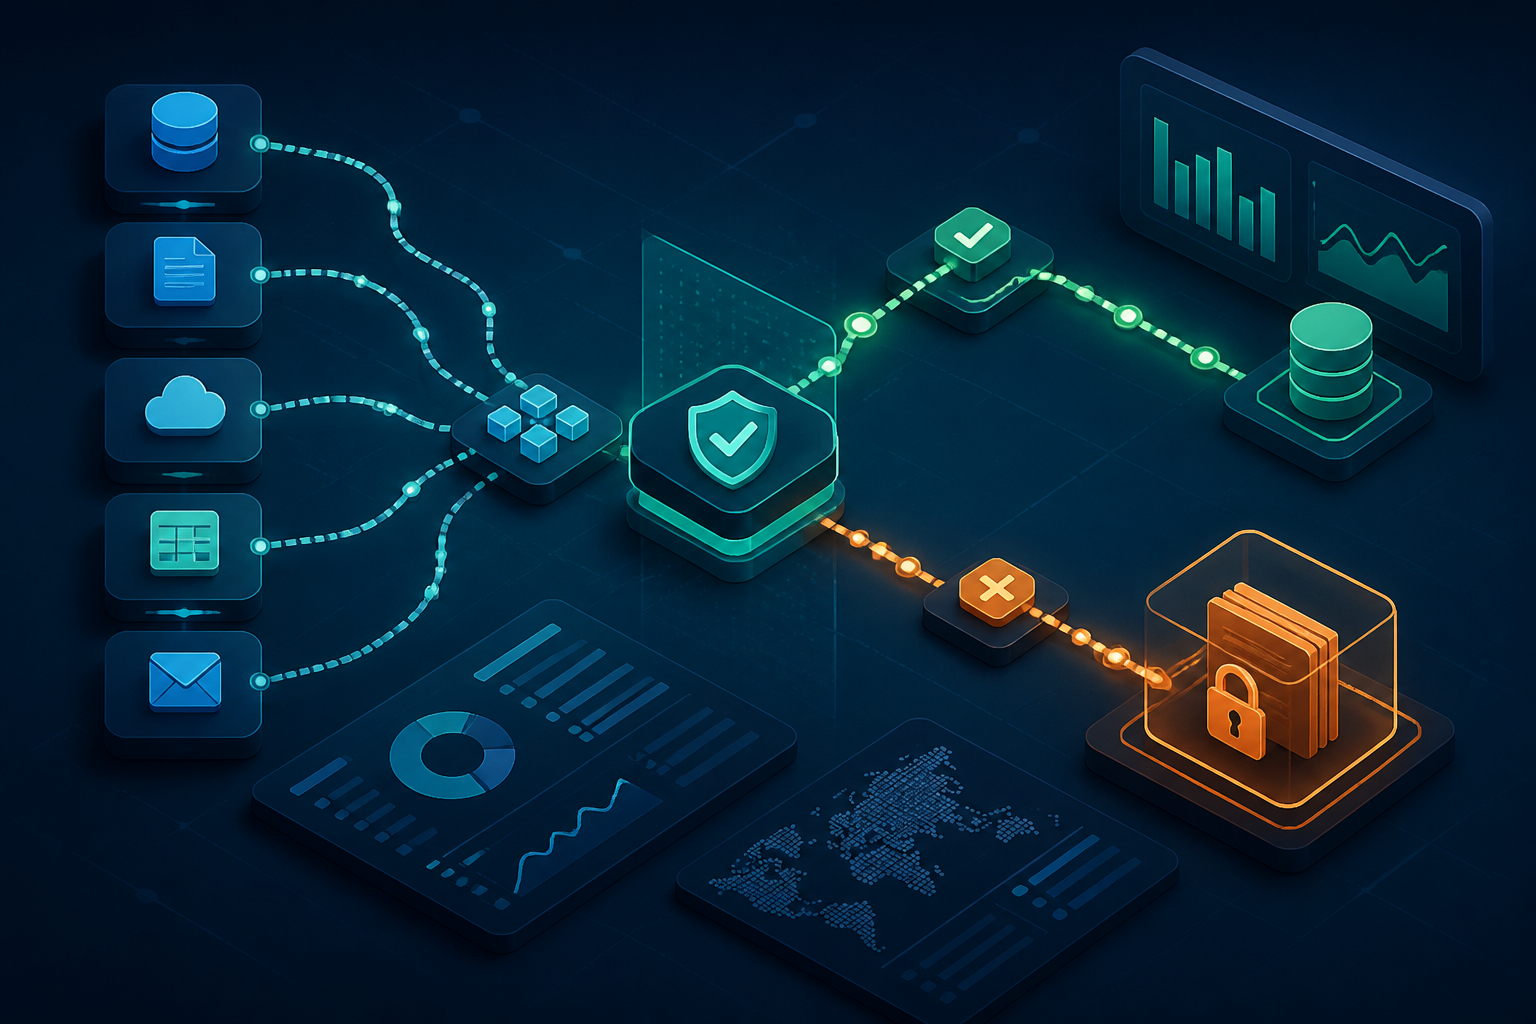
The most costly mistakes in n8n workflows are often not the workflows that fail. Rather, the harder-to-detect issue is a workflow that completes with a success status but carries incorrect data: empty email addresses, prices read as text, shifted dates, or field names changing from customer_email to email.
This problem arises because many workflows only check if a node has executed successfully. However, technical success and data correctness are two different things. An API can return an HTTP 200 response, but the content of that response may not meet the needs of the next step.
This is where data validation comes into play. Validation is a check to ensure that data has a reasonable form, content, and value before being passed on. In n8n, data from previous nodes can be referenced through expressions and field mapping in the workflow interface. ([docs.n8n.io](https://docs.n8n.io/data/data-mapping/data-mapping-ui/?utm_source=openai))
Treat Each Stage as a Checkpoint
Imagine a workflow as a sorting path for items in a warehouse. Incoming items need to have their labels, quantities, and conditions checked before being sent to their destination. If checks are only performed at the last door, incorrect items have already passed through many processes.
An n8n workflow should have several “checkpoints”:
- After data entry: ensure the payload is not empty and that key fields are present.
- After transformation: check if field names, data types, and formats are consistent.
- Before sending to another system: ensure the data meets the requirements of the target API.
- After receiving a response: check if the operation actually produced the expected ID or status.
This pattern does not mean that every node must be filled with dozens of conditions. The focus is on identifying points that are most at risk of causing data damage or actions that are difficult to reverse.
Start with a Simple Data Contract
Before adding IF nodes or Code, first write down the expected data structure. There’s no need to immediately use a complex schema system. A small list is sufficient:
{
  "order_id": "ORD-1001",
  "customer_email": "customer@example.com",
  "total": 125000,
  "currency": "IDR",
  "status": "paid"
}
This data contract answers several basic questions: which fields are mandatory, what are their data types, what values are allowed, and when is the data considered invalid.
For example, order_id must not be empty, total must be a positive number, while status may only contain paid, pending, or cancelled. Such rules make the workflow easier to understand when maintained weeks or months later.
Normalize Before Validation
Data from webhooks, RSS feeds, spreadsheets, or APIs often use different formats. Emails may have leading spaces, phone numbers may use a plus sign or zero, and field names may vary between sources.
Therefore, normalization should be done before validation. Use nodes like Edit Fields to standardize names and data formats. For example, change the following variations into one format:
email,email_address, andcustomerEmailtocustomer_email.- Price values in string format like
"125000"to numbers. - Status text like
PAIDandPaidtopaid.
Understanding the difference between mapping and transformation is important. n8n documentation explains that data mapping means taking data from the previous node, not changing its content. Format changes need to be done intentionally through expressions or transformation nodes. ([docs.n8n.io](https://docs.n8n.io/data/data-mapping/data-mapping-ui/?utm_source=openai))
Use Valid and Invalid Paths
After data is normalized, create decision paths. IF nodes are suitable for simple checks, such as whether an email exists or if the total is greater than zero. For multiple status options, Switch nodes or a series of conditions can clarify the flow.
Example logic:
- Check if
order_id,customer_email, andtotalare available. - If not, send the data to a quarantine path.
- If yes, check if the status is among the allowed list.
- Only data that passes all checks is forwarded to the CRM or payment service.
The invalid path does not have to end with a hard error. For operational data, it is more useful if the items are stored in a special table, sent as internal notifications, or flagged for manual review. This way, a single bad data point does not always halt the entire process.
Differentiate Between Empty Data, Incorrect Data, and Unknown Data
These three conditions are often mixed up, yet they require different handling.
- Empty data: fields are missing or their values are empty. Example: customer email not sent.
- Incorrect data: fields exist, but their format is incorrect. Example: total contains the text “one hundred thousand.”
- Unknown data: format is correct, but the value is not understood by the workflow. Example: a new status
refundedappears after the source system adds a feature.
Empty data can usually be rejected or requested again. Incorrect data needs to be corrected or quarantined. Unknown data should be treated cautiously, especially if the workflow will take actions like sending messages, creating invoices, or changing customer statuses.
Do Not Lose Track When Transforming Data
Overly aggressive transformations can create new problems. For example, a workflow replaces the entire content of an item with processing results, causing source information like URLs, timestamps, or execution IDs to be lost.
Keep important metadata alongside normalized data:
sourceto know the origin of the data.received_atto record when the data was received.validation_statusto distinguish between valid and rejected.validation_errorsto explain the reasons for rejection.
This also helps when the workflow uses data from multiple branches. n8n has an item linking mechanism to maintain the relationship between processed items and their sources. If this relationship is lost at a certain node, expressions referring to previous data may encounter issues. ([docs.n8n.io](https://docs.n8n.io/data/data-mapping/data-item-linking/item-linking-node-building/?utm_source=openai))
Test with Bad Data, Not Just Ideal Data
Workflows are often tested using a single neat example. However, issues usually arise from edge cases: missing fields, empty arrays, special characters, changed API responses, or data containing more items than expected.
Create a small test set that includes:
- Complete and valid data.
- Missing mandatory fields.
- Empty or zero values.
- Different date formats.
- Unknown statuses.
- API responses without properties that are usually available.
The data set for testing can also assist in the debugging process. n8n documentation provides discussions on pinning and mocking data, while previous executions can be reloaded for analysis or retrial. ([docs.n8n.io](https://docs.n8n.io/workflows/sharing/?utm_source=openai))
What You Can Do Now
- Choose one workflow that frequently modifies or sends data.
- Write down three to five of the most important fields.
- Add one normalization node before the main process.
- Create an IF check for mandatory fields and critical values.
- Provide a quarantine path for failed data.
- Store the reasons for failure, not just the label “invalid.”
- Test the workflow with at least five examples of bad data.
Validation is not a guarantee that the workflow will never go wrong. However, validation makes errors more visible, easier to trace, and less likely to spread to other systems. Good automation is not only capable of performing tasks without manual clicks but also knows when to stop and request human review.
Sources & Further Reading
- Referencing data in the UI - n8n Docs
- Item linking for node creators - n8n Docs
- Sharing - n8n Docs
- All executions - n8n Docs
– Rio Yotto @rioyotto