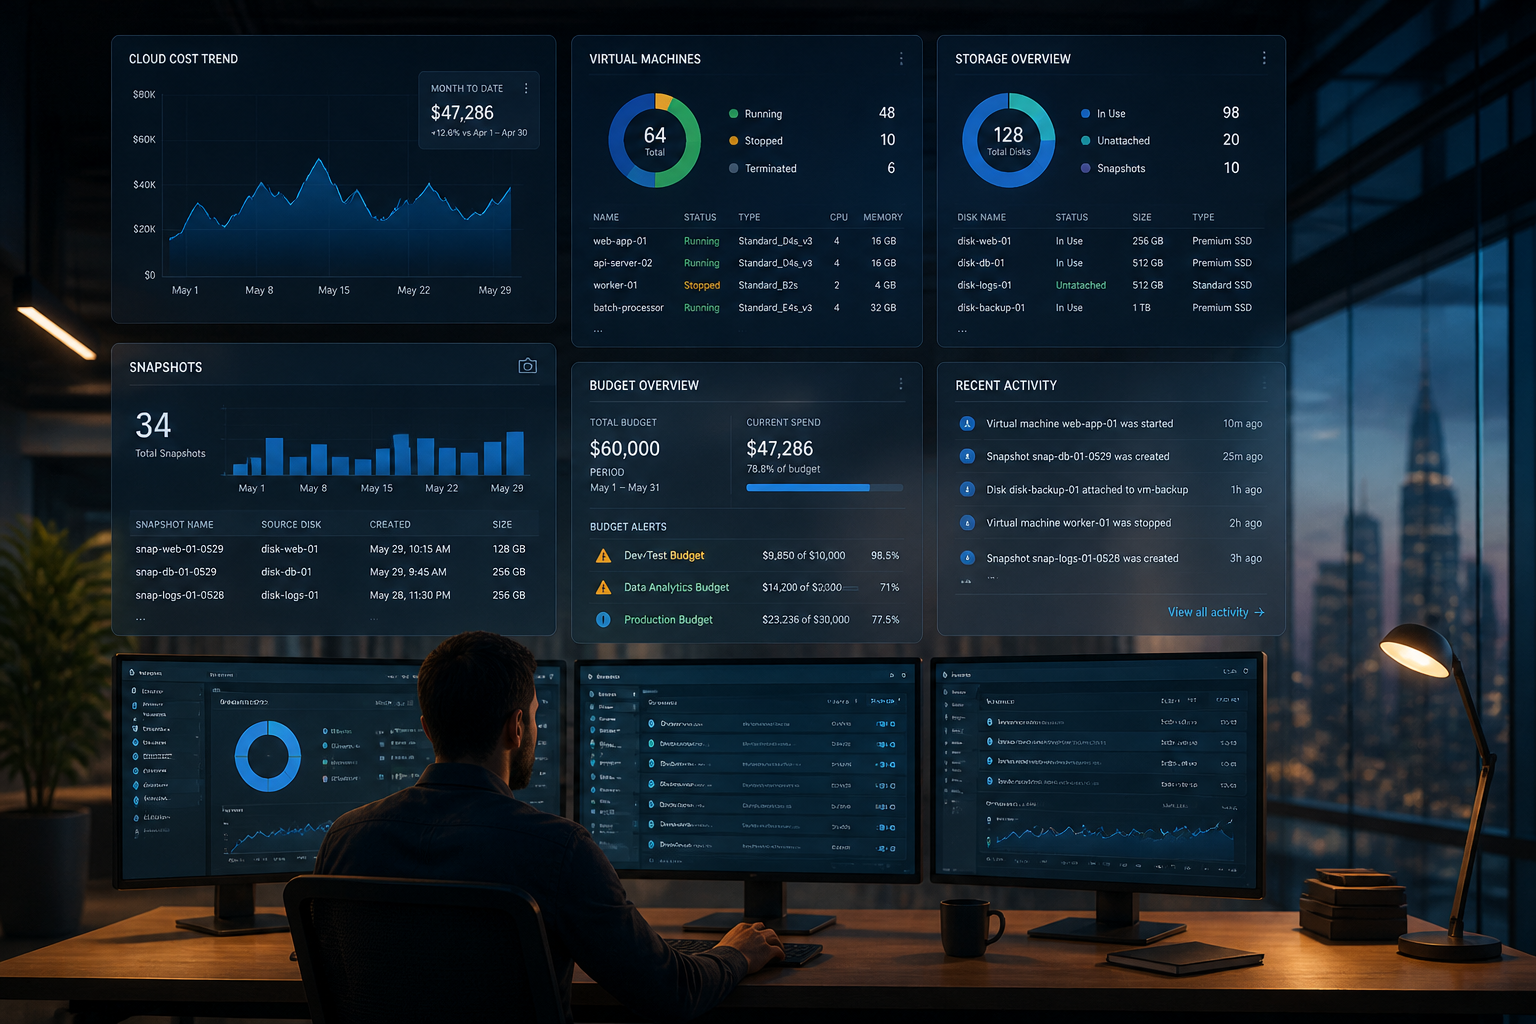
Cloud bills often feel like a leaking faucet: not flooding the room immediately, but dripping continuously every hour. A forgotten test server, a disconnected disk, or old snapshots piling up can become routine costs without ever appearing on the application dashboard.
The issue is not always that companies are using too much computing power. Often, the problem is that no one really knows which resources are still needed, who owns them, and when they can be deleted. Therefore, cloud savings should start with visibility, not by blindly reducing server specifications.
Start by separating costs by service
The first step is to look at the bill by service type, not just the total monthly amount. Group costs into computing, storage, database, data transfer, IP addresses, and other supporting services.
In AWS, Cost Explorer can be used to analyze costs and usage by period, service, region, or specific filters. Azure has Cost Analysis to view current costs, trends, and estimated bills. Google Cloud provides cost reports and budgets that can be limited by account, project, service, or label.
The goal is not just to find the largest number. High computing costs may indeed come from the main application and be difficult to reduce without testing. Conversely, smaller but continuously rising storage costs may indicate old data that never had a retention policy.
Four often-overlooked cost sources
1. Disconnected disks
When a VM is deleted, additional disks do not always get deleted as well. Depending on the configuration, disks can remain available to prevent data loss. This is useful if the VM deletion is temporary, but it becomes wasteful if the resources are from experiments months ago.
In AWS, EBS volumes with an available status mean they are not currently attached to an instance. This status is not proof that the volume can be deleted, but it is a starting list that needs to be checked. Before deleting, ensure that the data is no longer needed or that a recoverable copy exists.
2. Snapshots and backups without expiration
Backups are important, but backups without retention rules will turn into permanent archives. Daily snapshots initially created for recovery purposes can continue to accumulate for months.
EBS snapshots are incremental: after the initial snapshot, only the changed data blocks are stored. However, deleting one snapshot does not necessarily remove all related data because those blocks may still be used by other snapshots. This means that snapshot management needs to follow a policy, not be done randomly.
Establish simple rules, such as keeping daily backups for seven days, weekly backups for four weeks, and monthly backups for six months. These numbers are not universal. Financial applications, internal systems, and small websites may have different retention needs.
3. Always-active development and staging environments
Production servers usually have clear owners and operational schedules. Development or staging environments are often created quickly to test features and then forgotten. If those servers have databases, disks, IP addresses, and additional services, costs can arise from multiple sources at once.
Use an automated schedule to shut down non-production environments outside of working hours. For teams working from 9 AM to 6 PM, turning off resources at night and on weekends can significantly reduce active hours. Always test the impact, especially if there are backup processes, scheduled jobs, or access from team members in different time zones.
4. Egress data and cross-region resources
Many people pay attention to server and storage prices but forget about data transfer costs. CDNs, cross-region backups, database replication, and APIs sending large files can increase egress data usage.
Do not immediately conclude that all data transfers should be reduced. Cross-region replication may indeed be necessary for service resilience. What needs to be done is to understand the data paths: what data is leaving, from which services, to which regions or providers, and whether the transfer sizes are reasonable.
Tags are not decoration: use them to identify cost owners
Tags or labels are simple metadata like environment=production, team=marketing, or owner=andi. With consistent naming, costs can be grouped by application, team, project, and environment.
A good tagging scheme does not need to be lengthy. Start with four columns:
- application: name of the application or service;
- environment: production, staging, or development;
- owner: team or person responsible;
- expiry: date for evaluating or deleting temporary resources.
Tags do not automatically resolve waste. Tags only help answer an important question: who needs to check this resource? In AWS, certain tags can be enabled as cost allocation tags to help group costs. In Google Cloud, labels can be used as part of budget scopes and cost reports.
Don’t just set alerts, take action after alerts
Budgets and notifications are important, but alert emails do not automatically stop usage. Google Cloud explicitly distinguishes budget alerts from spending limit mechanisms: alerts notify that costs are approaching a threshold, but do not always prevent services from continuing to run.
Therefore, each alert should have a follow-up procedure. For example:
- Check the services experiencing cost increases.
- Compare with deployment changes or ongoing campaigns.
- Check temporary resources, disconnected disks, snapshots, and data transfers.
- Determine if the increase was indeed planned.
- If not, stop or modify the resource after the owner agrees.
What you can do now
Set aside 30–60 minutes each week to create an inventory of resources. Start with a list of VMs, disks, snapshots, databases, storage buckets, public IPs, and non-production environments. Add columns for owner, purpose, creation date, and the last decision: retain, modify, or delete.
For resources with unclear ownership, do not delete them immediately. Assign a temporary tag like review-needed=true, then set a review deadline. If no owner confirms the need after that period, then create a plan for deletion or moving to cheaper storage.
Healthy cloud savings do not mean cutting all resources to the point where applications become fragile. The focus should be on ensuring every cost has a reason: serving users, maintaining recovery, meeting security needs, or supporting ongoing work. If a resource cannot justify its benefits, it is the first candidate to be reviewed.
Sources & further reading
- Analyzing your costs and usage with AWS Cost Explorer
- Create, edit, or delete budgets and budget alerts — Google Cloud Documentation
- Get started with Cost Management reporting — Microsoft Learn
- Create an inventory of your EBS volumes — Amazon EBS
- How Amazon EBS snapshots work — Amazon EBS
- Tag your Amazon EC2 resources — Amazon EC2
– Rio Yotto @rioyotto