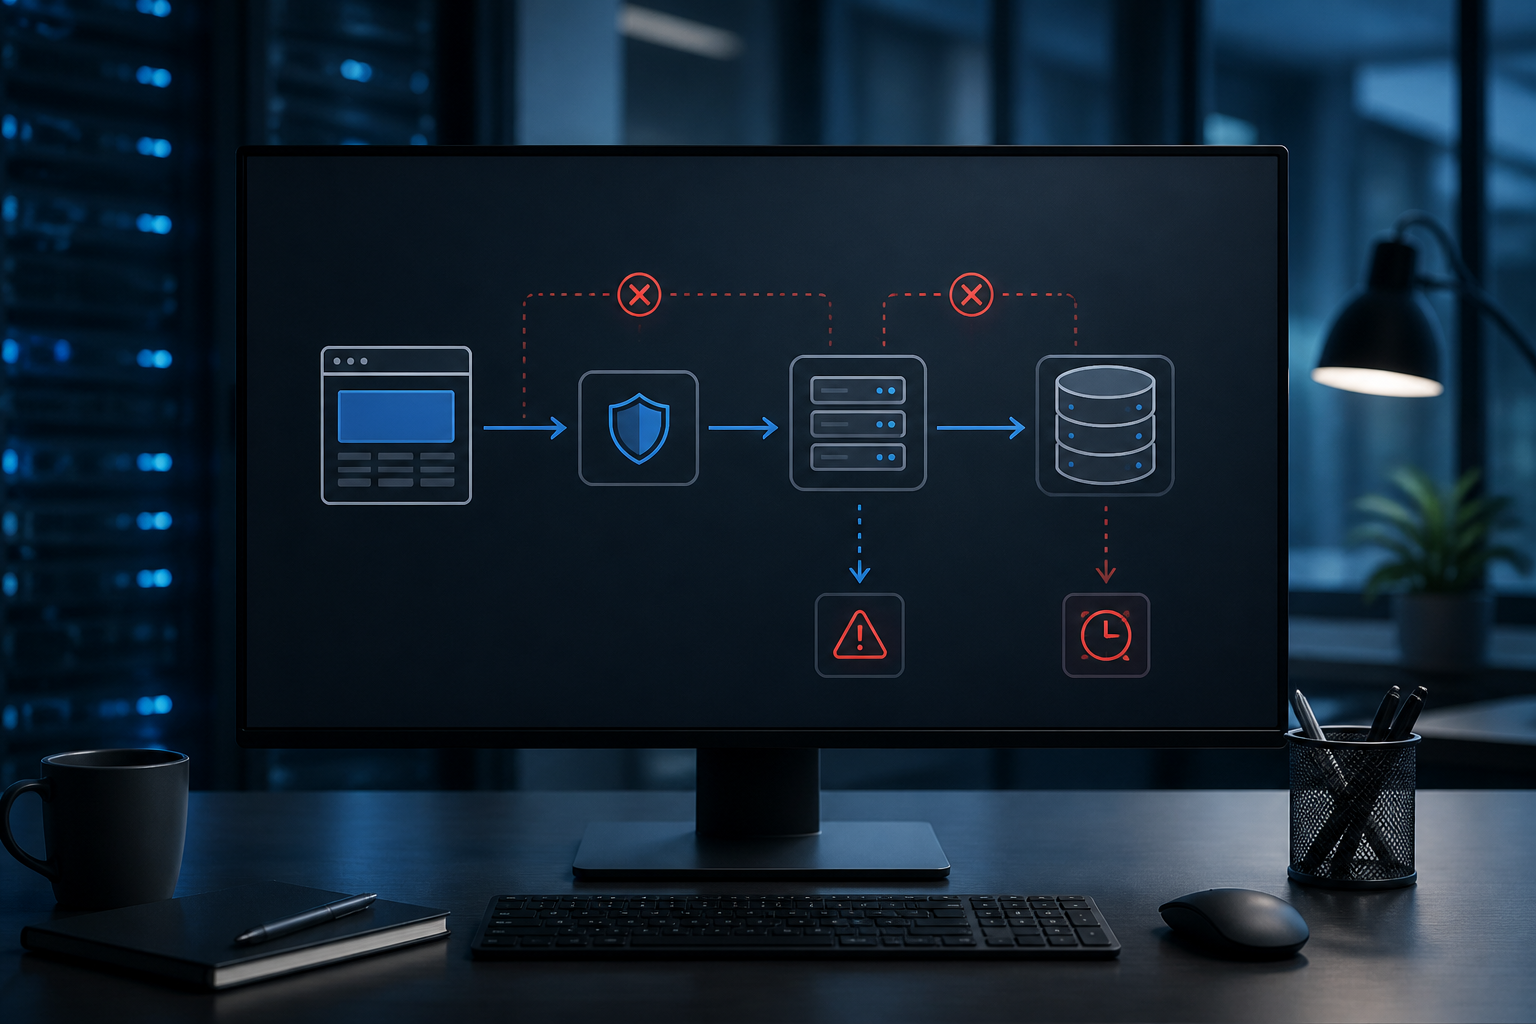
A webpage suddenly displaying 502 Bad Gateway or 504 Gateway Timeout often leads people to immediately blame the main server. However, there are usually several layers between the browser and the application: CDN, reverse proxy, web server, PHP-FPM, API, and database.
Therefore, the first step is not to immediately restart all services or upgrade the VPS specifications. First, understand the type of error, then trace the request path from front to back.
Difference between 502 and 504
502 Bad Gateway means that the server acting as a gateway or proxy received an invalid response from the server behind it. For example, Nginx forwards a request to PHP-FPM, but the connection is closed abnormally or the response received is not as expected. This definition aligns with RFC 9110 and MDN documentation. ([developer.mozilla.org](https://developer.mozilla.org/en-US/docs/Web/HTTP/Reference/Status?utm_source=openai))
504 Gateway Timeout means that the gateway or proxy did not receive a timely response from the upstream server. Upstream refers to the services behind the proxy, such as PHP applications, internal APIs, or databases called by the application. Thus, 504 is more related to timeout issues, although the underlying causes can vary. ([developer.mozilla.org](https://developer.mozilla.org/en-US/docs/Web/HTTP/Reference/Status/504?utm_source=openai))
A simple analogy: 502 is like receiving a broken or nonsensical answer from the kitchen. 504 is like waiting too long until the waiter decides that the order is never going to be completed.
Do not immediately change the timeout
Increasing the timeout can sometimes help requests that naturally take a long time. However, it is not a solution for stuck queries, PHP processes running out of workers, or failed database connections.
If the timeout is increased without identifying the root cause, the problematic requests will actually take longer. During high traffic, many such requests can fill up workers and slow down other pages.
In Nginx, for example, proxy_read_timeout sets how long the proxy waits for a response from the target server. This setting only changes the wait limit, not fixing the slow or unhealthy upstream service. ([nginx.org](https://nginx.org/en/docs/http/ngx_http_proxy_module.html?utm_source=openai))
Diagnostic steps to try
1. Ensure the error occurs on all pages
Try opening the homepage, login page, admin page, and API endpoint if available. Note the patterns:
- If all URLs fail, the problem is likely with the proxy connection to the origin, the web server, or the server being down.
- If only one page fails, suspect the application code, database query, API integration, or specific data.
- If only certain users experience issues, check the network, VPN, DNS, or proxy configuration on the user side.
Testing from different networks is also useful. Try mobile connections, other devices, or external monitoring services. The goal is not just to ensure the website can be opened, but to find out if the failure is general or local.
2. Check the status of services from the backend layer
If you have server access, check if essential services are still running. For example, on a Linux system with systemd:
sudo systemctl status nginx
sudo systemctl status php-fpm
sudo systemctl status mysql
The name of the PHP-FPM service may vary, for example, php8.2-fpm. Do not copy the service name verbatim; adjust it to the installed version.
Also, check CPU, RAM, and disk usage. Exhausted RAM can cause processes to be terminated by the system. A full disk can prevent the application from writing sessions, logs, caches, or temporary files.
3. Read logs at the same time
Do not just look at the latest logs in general. Match the time when the error occurred with entries across several layers:
- Nginx or Apache logs to see connection failures to upstream.
- PHP-FPM logs to see if workers stopped, are full, or reached process limits.
- Application logs to find exceptions, requests that took too long, or API failures.
- Database logs to see disconnected connections, locks, or queries running too long.
Messages like connection refused usually have different meanings from upstream timed out. The former points to a service that is not accepting connections. The latter indicates that a connection may have been successfully established, but the response did not complete within the timeout.
4. Separate application issues from infrastructure issues
If a simple endpoint like /health succeeds, but the report page fails, the underlying infrastructure is likely still alive, and the problem lies within the application process or its dependencies.
The health check endpoint should be lightweight. Do not make it run large reports or call all external services. Such checks should simply ensure the application can receive requests and, if necessary, connect to critical dependencies.
5. Test dependencies one by one
Modern applications rarely work alone. A single page can call a database, payment API, email service, object storage, and authentication system. If one of the services is slow, the main request can also be delayed.
Use response times and logs to identify which dependencies are the slowest. If possible, set separate timeouts for each outgoing call. The payment API timeout does not have to be the same as the database query timeout.
What does this mean for website owners?
Error 502 or 504 is not always a sign that the server needs to be replaced. Often, the issues are more specific: one process is stuck, there are too few workers, queries are inefficient, database connections are exhausted, or external services are unresponsive.
The important thing is to have basic observability: easily searchable logs, response times, service status, resource usage, and request information that is safe to trace. Without this data, the troubleshooting process becomes guesswork.
What can be done now
- Create a list of components that the request passes through: CDN, proxy, web server, runtime, application, database, and external APIs.
- Provide a lightweight health check page or endpoint.
- Ensure logs capture timestamps, endpoints, and request durations without leaking passwords or tokens.
- Set timeouts for outgoing connections and use retries cautiously.
- Test critical pages after each configuration change.
- Do not increase the timeout before knowing if the source is truly a slow process.
If the website is managed by a hosting provider, send the time of occurrence, failed URLs, error codes, and results of tests from different networks. This information is much more useful than simply saying, "The website is down."
In essence, 502 and 504 are clues about inter-service relationships, not final diagnoses. By distinguishing between invalid responses and delayed responses, you can narrow down the problem and choose more sensible fixes.
Sources & further reading
- HTTP response status codes - MDN Web Docs
- 504 Gateway Timeout - MDN Web Docs
- RFC 9110: HTTP Semantics
- NGINX ngx_http_proxy_module Documentation
– Rio Yotto @rioyotto