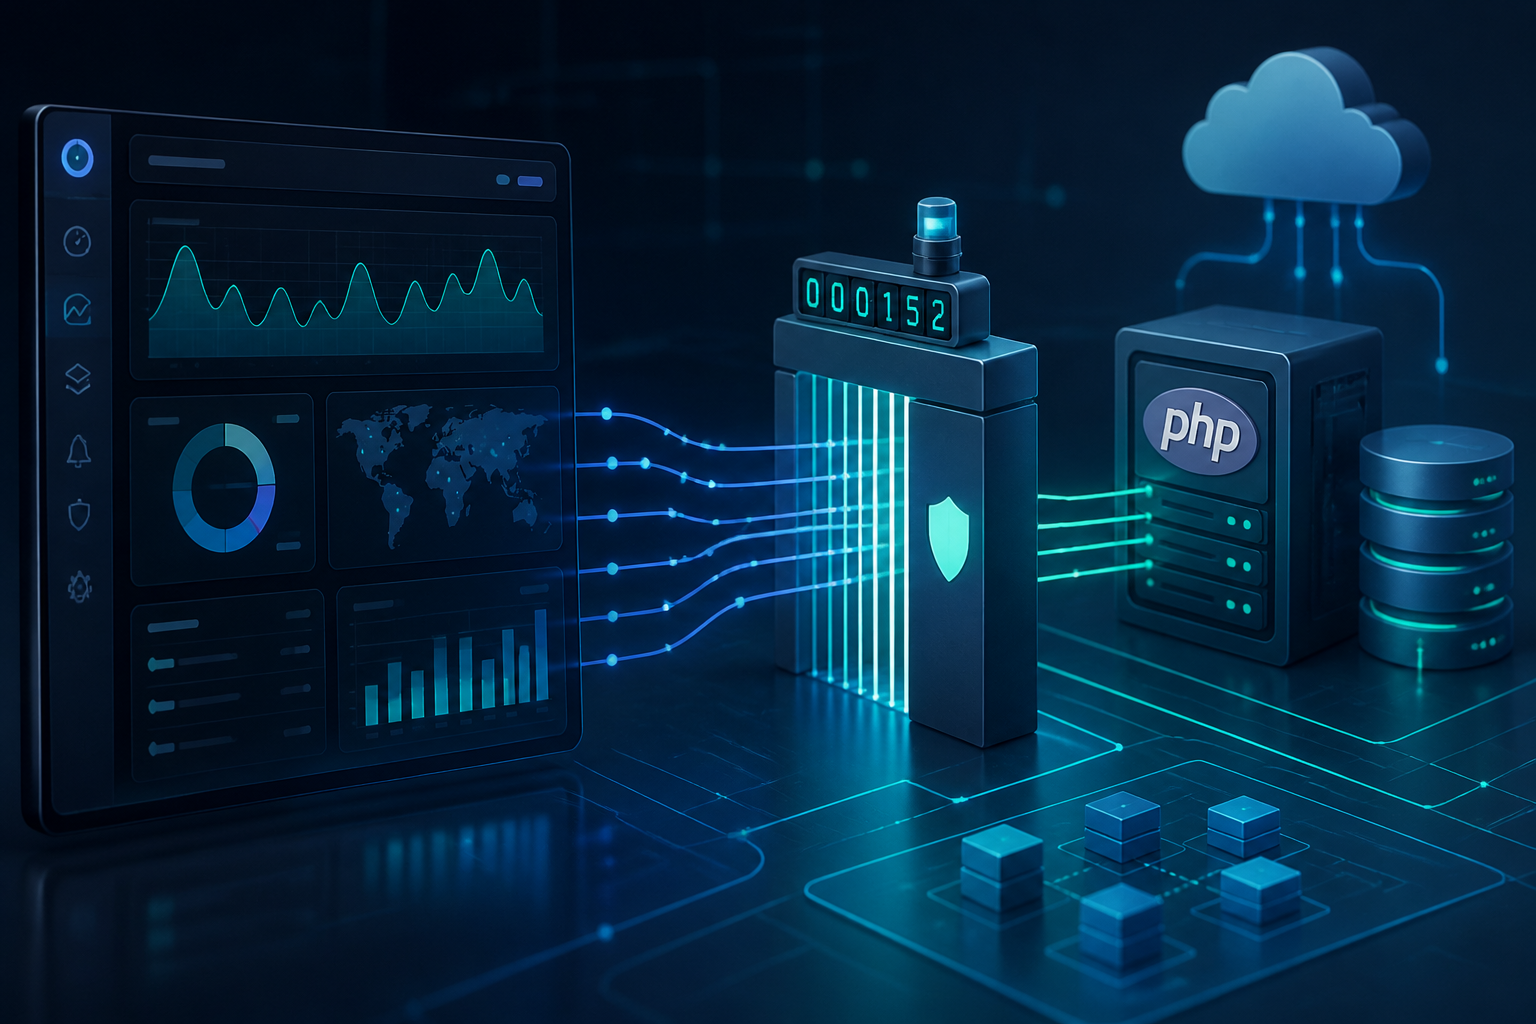
An API endpoint may seem fine when only a few users are using it. Problems usually arise when there are bots making repeated requests, misconfigured scripts, or frontend features inadvertently calling the endpoint multiple times. Without restrictions, the PHP server can continue processing requests that are actually unnecessary.
This is where rate limiting comes in handy. Simply put, rate limiting is a rule that restricts how many requests can be made by a single user, IP address, token, or application within a certain period. For example, one IP address may access the search endpoint a maximum of 60 times per minute.
Rate limiting is not a substitute for authentication and is not a standalone solution for large-scale attacks. However, it is a relatively simple layer of protection that is often overlooked when an application starts receiving traffic from outside.
Why is request limiting important?
Without rate limiting, a single endpoint can become a weak point. The login endpoint can be used to try many password combinations. The search endpoint can be called thousands of times to drain database resources. The email sending endpoint can be abused to send spam.
Even without malicious intent, normal users can also create a significant load. For example, JavaScript on a page performs polling every second, then is opened by hundreds of users. From the browser's perspective, everything seems normal. From the server's perspective, the number of queries and connections can increase rapidly.
Practical analysis: rate limiting forces us to determine the value of a request. The product listing endpoint may require a fairly loose limit, while the login, password reset, and OTP sending endpoints should have much stricter rules.
Determine what to limit
A common mistake is using a single number for all endpoints. In fact, the needs of each feature are different. Before writing code, determine the following three things:
- Limiter identity: is it based on IP, user ID, API key, session, or a combination of several identities?
- Time window: is the limit calculated per second, minute, hour, or day?
- Response when the limit is reached: does the server return HTTP 429, ask the user to wait, or implement a queue?
For public endpoints, the IP address is often a starting point. For logged-in users, the user ID or API key is usually more accurate. If only using IP, several users on a single office network or mobile network could be affected by the same limit.
Correct response when the limit is exceeded
When requests are denied due to being too frequent, use the HTTP status 429 Too Many Requests. This status clearly signals to the client that the issue is not that the endpoint was not found or that the server encountered a general error.
The response can also include simple information such as when the client can try again. The Retry-After header is useful for providing a wait time in seconds.
HTTP/1.1 429 Too Many Requests
Retry-After: 30
Content-Type: application/json
On the JSON side, the format can be made consistent:
{
  "error": "rate_limit_exceeded",
  "message": "Too many requests. Please try again later.",
  "retry_after": 30
}
Messages for users can be friendly, but do not disclose internal details such as counter storage structure or overly specific security rules.
Simple example with PHP and Redis
For applications running on a single server, a simple counter may be stored in local memory. However, this approach becomes problematic when the application runs on multiple servers. Each server may have its own limit record, leading to inconsistent restrictions.
Redis is often used to store counters with an expiration time. The following example uses the fixed window concept: each IP has a request quota within one minute.
<?php

$key = 'rate_limit:' . ($_SERVER['REMOTE_ADDR'] ?? 'unknown');
$limit = 60;
$window = 60;

$current = $redis->incr($key);

if ($current === 1) {
    $redis->expire($key, $window);
}

if ($current > $limit) {
    http_response_code(429);
    header('Retry-After: ' . $window);
    echo json_encode([
        'error' => 'rate_limit_exceeded',
        'message' => 'Too many requests.'
    ]);
    exit;
}
This example is still simple. In a production implementation, pay attention to atomic operations, how to determine the actual wait duration, logging, and IP address validation if the application is behind a reverse proxy.
Fixed window, sliding window, or token bucket?
Fixed window is the easiest to understand: for example, 60 requests from 12:00:00 to 12:00:59. The downside is that users can send many requests at the end of one window and the beginning of the next window.
Sliding window counts requests within a continuously moving time range. The result is smoother, but storage can be more complex because the system needs to track the time of each request or create more detailed aggregations.
Token bucket works like a bucket filled with tokens. Each request takes one token, while new tokens are added periodically up to a certain limit. This model allows for small spikes that are still reasonable while maintaining average traffic.
For many small applications, a fixed window is sufficient as a starting step. Do not make the algorithm too complicated before understanding the actual traffic patterns.
Don't forget to limit sensitive endpoints
Some endpoints deserve special limits:
- Login and password checks.
- Requests for OTP codes or password resets.
- Email sending, notifications, and contact forms.
- Searches that run heavy queries.
- Data exports or report generation.
- Endpoints that call paid third-party services.
For login, limiting based on IP alone is not enough. Also add limits based on account identity or a combination of IP and normalized username. This way, attackers cannot easily test many passwords against one account, but users on a shared network are not immediately blocked entirely.
What does this mean for us?
Rate limiting should be treated as part of API design, not a patch after the server has issues. Every public endpoint needs to have usage expectations: how many normal requests, what is considered unusual, and how the client should react.
What can be done now is to start with the most at-risk endpoints. Record the number of requests, measure normal usage over several days, then set limits with enough room. Add a 429 response, document the rules for the frontend, and ensure clients do not retry without a pause.
Finally, monitor the metrics. If many normal users are hitting the limit, reset the policy. If one endpoint frequently receives repeated requests from the same source, check whether the cause is a frontend bug, incorrect integration, or abuse patterns.
– Rio Yotto @rioyotto